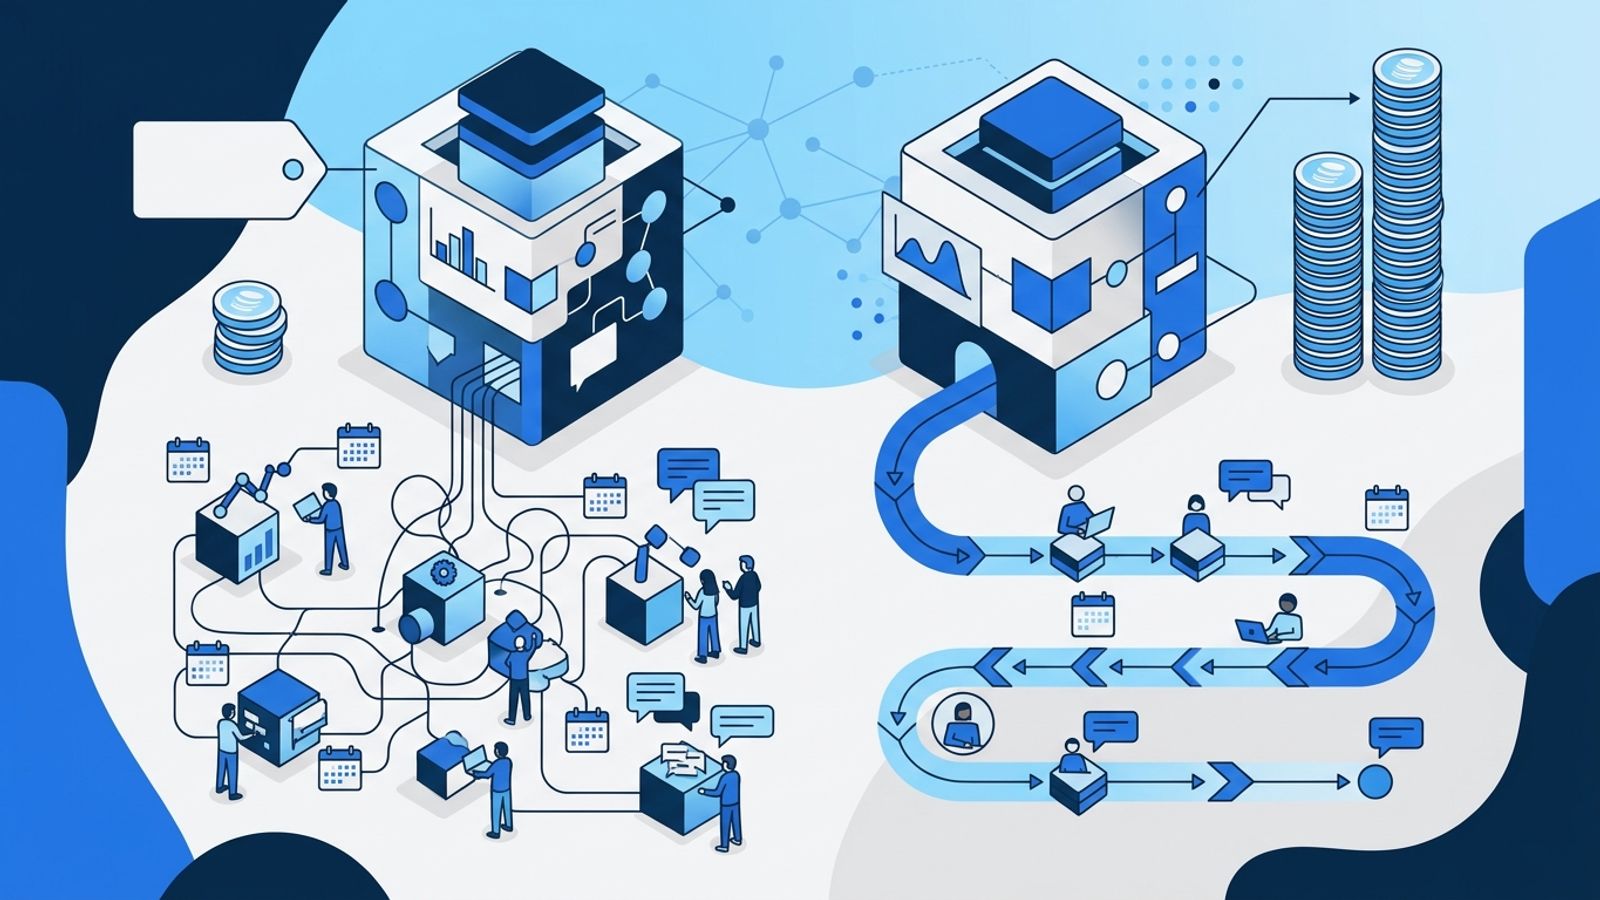
A lower quoted AI price can look like an obvious reason to switch. But the price of a model is only one part of what a task costs you. If an answer needs several edits or a staff member must check every detail, the cheaper option may not save time or money overall.
For an appointment-centric business, compare models on work you actually do: drafting a reply to a booking inquiry, summarizing a client message or preparing a promotion for review. Measure the complete workflow, not just the model’s price.
Why headline price is incomplete
Recent model coverage offers a useful example. OpenAI introduced GPT-6 Sol and GPT-6 Luna on September 22, 2026, and said their API prices were 50% lower than GPT-5.6 promotional pricing. API means a connection that lets software send requests to an AI model. OpenAI attributed the lower prices to improvements in caching and inference, the processes used to handle requests and generate answers, according to the report.
The same report describes OpenAI’s AutomationBench results: the benchmark tests end-to-end business workflows using 47 tools, and OpenAI reported GPT-6 Sol scored 33.2% at a cost of $0.27 per task. Those are OpenAI-reported results, not a direct measure of how well a model handles your booking messages, brand voice or approval process. Treat a benchmark as one signal, then test the work you need done.
OpenAI also said GPT-6 Sol made about half as many mistakes as its predecessor in an internal evaluation based on conversations where users had flagged model errors. The company cautioned that those flagged conversations were not representative of typical use. Both statements come from OpenAI’s reported evaluation. That is a reason to check how a model performs on your own examples rather than assuming a published result predicts your results.
Price the whole workflow
For each model, estimate the cost of completing the task, not just generating an answer:
Workflow cost = model or tool charges + staff review time + retries and rework + the likely cost of mistakes.
To estimate review time, record how long a staff member spends checking and correcting each output. Multiply those minutes by the hourly cost of that person’s time. Include time spent rewriting an answer, repeating a request or moving the work into the system your team uses.
For mistakes, consider the kind of task and the consequence of an error. A slightly awkward draft may need a quick edit. An incorrect promotion detail or a response that mishandles a client’s request may need more careful correction. You do not have to force every risk into a precise dollar amount: note which outputs need a human check and whether the model’s errors are acceptable for that use.
Keep the comparison consistent. If one model gets a detailed prompt and another gets a short one, you are not comparing the models fairly. Use the same instructions and the same information for each test. If a tool charges by subscription rather than by use, include the part of the subscription cost that belongs to the workflow you are evaluating.
Run a fair comparison
Choose one task with a clear standard for a good answer. For example, you might ask each model to draft a response to an inquiry using your approved service details, tone and booking instructions. Use real examples with personal details removed, and include ordinary requests as well as cases that require judgment or a careful handoff.
Score each output against the same checklist. Did it use the right service details? Did it follow your instructions? Was the tone suitable? Did it invent information or miss something important? Record the time needed to review it, any retries and the corrections made. A short, low-cost answer is not a good result if staff must rebuild it.
Do not average away a serious failure. If a model invents a price or gives an unsuitable answer to a sensitive client question, decide whether that task needs stronger instructions, a human review step or no AI assistance. Keep client-facing or clinical decisions under appropriate human oversight.
What to do before switching
- Pick one recurring task and write down what an acceptable result must include.
- Test each model with the same prompt and anonymized examples from your business.
- Track tool charges, staff review time, retries and corrections.
- Compare total workflow cost alongside accuracy and the level of risk you can accept.
- Repeat the check when you change the model, prompt or workflow.
A small, controlled comparison can help you decide whether a lower model price matters for the work your team actually does. If you want support testing accuracy, reliability and cost before customers see an AI tool, Vetraeus Evaluation is designed for that purpose.
- ai evaluation
- business costs
- appointment businesses
- marketing operations
- ai tools
Alan Jordan, founder and principal solutions architect. Data engineering, data science and business analytics for appointment-based businesses.